On-device AI: the LLM runs on your phone.
“On-device” is not a marketing synonym for “mobile app.” It means the model weights and inference run where you are — on the Android SoC, not in a data center.
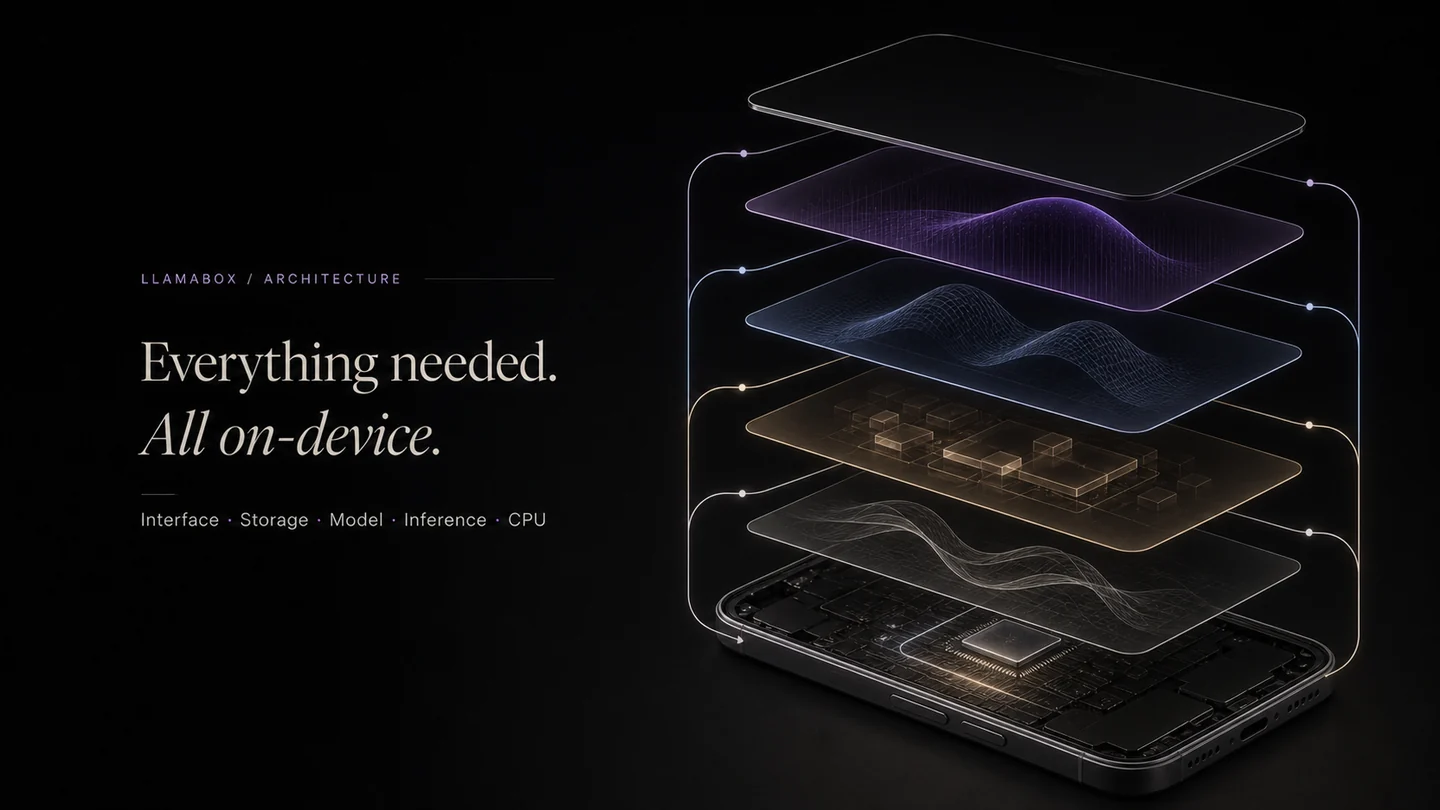
What is on-device AI?
On-device AI means machine-learning inference happens locally on the user’s hardware. For LlamaBox, that is your Android phone running a quantized LLM through llama.cpp. The forward pass, the chat history, and the generated text all stay inside the app process.
From on-device AI to on-device LLM
An on-device LLM is the text-generation subset of on-device AI. Instead of calling ChatGPT, Gemini, or Claude over the network, you load a GGUF file into app memory and run inference on the phone CPU. The device becomes the AI endpoint.
Stack (short)
- React Native 0.81 (New Architecture)
- llama.rn wrapping llama.cpp
- GGUF (Q4_K_M recommended)
- Zustand + SQLite + AsyncStorage
Privacy property
If generation never leaves the process, you do not need to “trust a privacy policy” for that step — you can reason about the architecture. See architecture and private ChatGPT alternative.
Performance expectations
Performance varies by phone, model, quantization, context and thermal state. Verified measurements will be published on the Tested devices page as they are recorded.
Use cases for on-device AI on Android
- Private drafts and journaling without cloud retention
- Offline travel, field work, and low-connectivity environments
- Sensitive professional notes (healthcare, legal, journalism, research)
- Air-gapped or policy-controlled environments
Next: GGUF guide · offline AI · Ollama Android alternative.
FAQ
What is on-device AI?
What is an on-device LLM?
Is on-device AI the same as offline AI?
Is on-device slower?
Does on-device AI require special hardware?
Why is on-device AI more private?
Try private offline AI on Android.
Install from Google Play, download a compatible model, then chat offline.