01
Airplane & offline travel
Draft emails, summarize notes, and brainstorm when Wi‑Fi is a myth. Model stays on the handset.
Travelers · digital nomads
Available on Google Play · Android 7.0+ · arm64
Run compatible GGUF models directly on Android with llama.cpp. Chat offline without uploading your conversations or creating an account.
Cloud AI asks you to trust a server.
LlamaBox lets you test the device.
Privacy is not a policy paragraph — it is the architecture. Inference has no LlamaBox server dependency, so you can switch the network off and check.
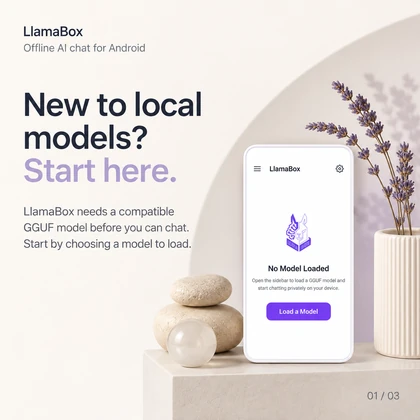
LlamaBox is publicly available on Google Play. Install the app, download or import a compatible model, and start chatting offline. Device compatibility and performance testing continue.
We publish these only once they are measured on real hardware. See tested devices for the data schema and methodology.
Not another chatbot wrapper. A local reasoning engine for people who need control, continuity, and silence.
Draft emails, summarize notes, and brainstorm when Wi‑Fi is a myth. Model stays on the handset.
Work with sensitive quotes and drafts without routing text through a third-party model API.
Explain concepts, quiz yourself, rewrite notes — without selling your study history to an ad stack.
Photograph a whiteboard, receipt, or diagram. Compatible multimodal models describe it locally on CPU.
Journaling, health questions, private plans — LlamaBox does not upload conversations for cloud-model training.
Experiment with GGUF models, sampling knobs, and system prompts on real mobile hardware.
Useful AI where bandwidth is expensive or censored. Download once; think offline afterwards.
Generate a reply, then listen with system TTS while you walk, cook, or drive (safely parked).
A complete local-LLM toolkit — models, chat, vision, voice, and visibility into what the phone is doing.
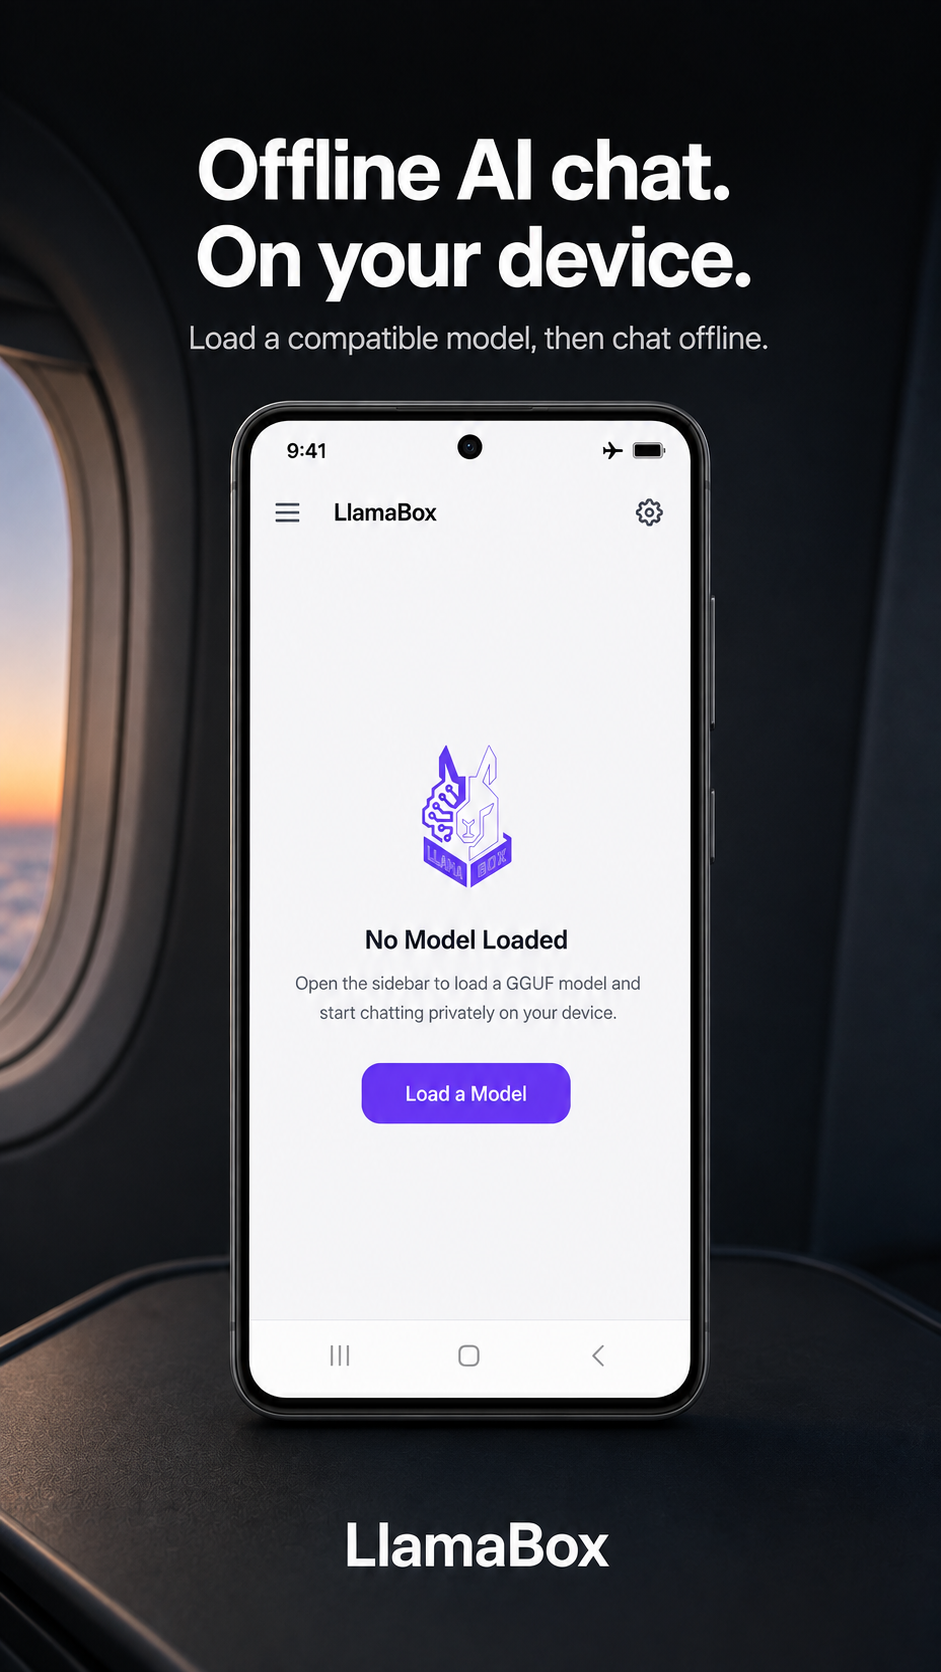
Once a compatible model is stored on the device, generation does not require the network. Airplane mode is a feature, not a failure state.
Camera or gallery → local encode → answer. Requires a compatible multimodal model and a matching projector. Image encoder is forced to CPU so the UI stays alive.
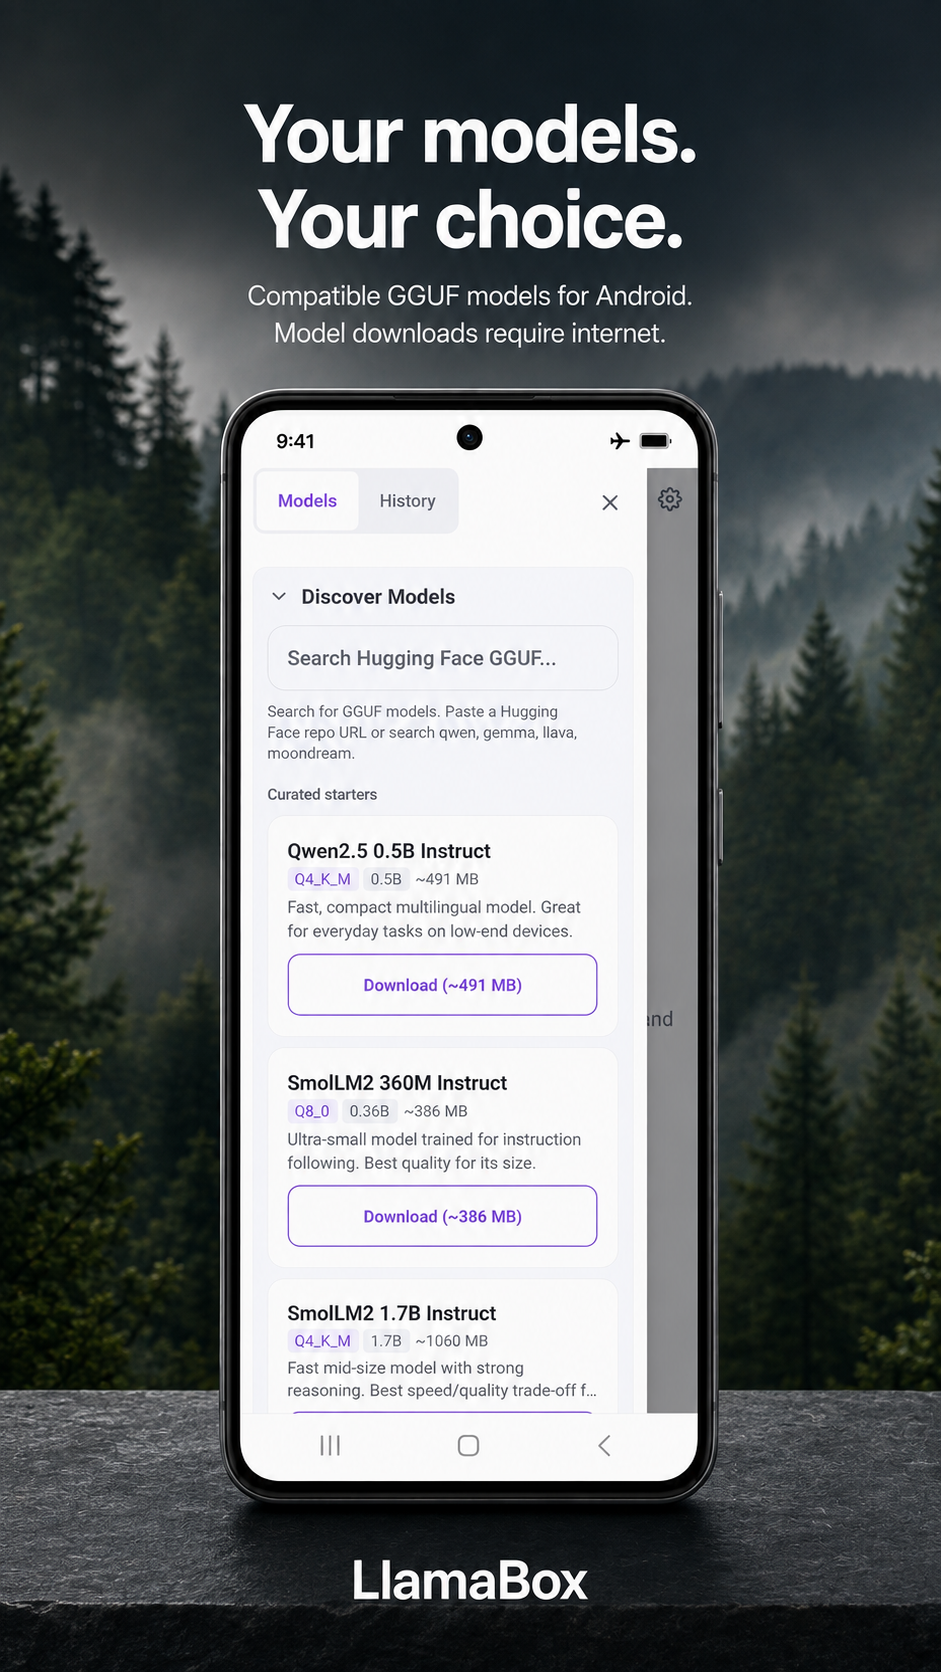
Download curated GGUF builds or import your own. Q4_K_M is recommended for mobile speed/quality — not a universal compatibility promise.
System TTS reads answers aloud for hands-free follow-through. Behaviour depends on the Android TTS engine you have selected.
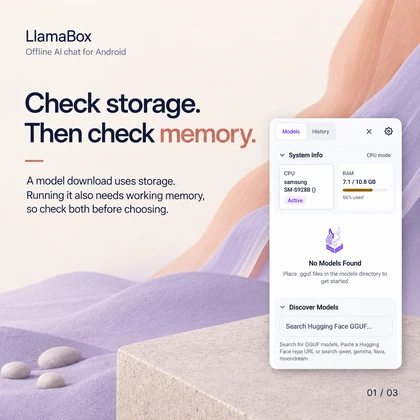
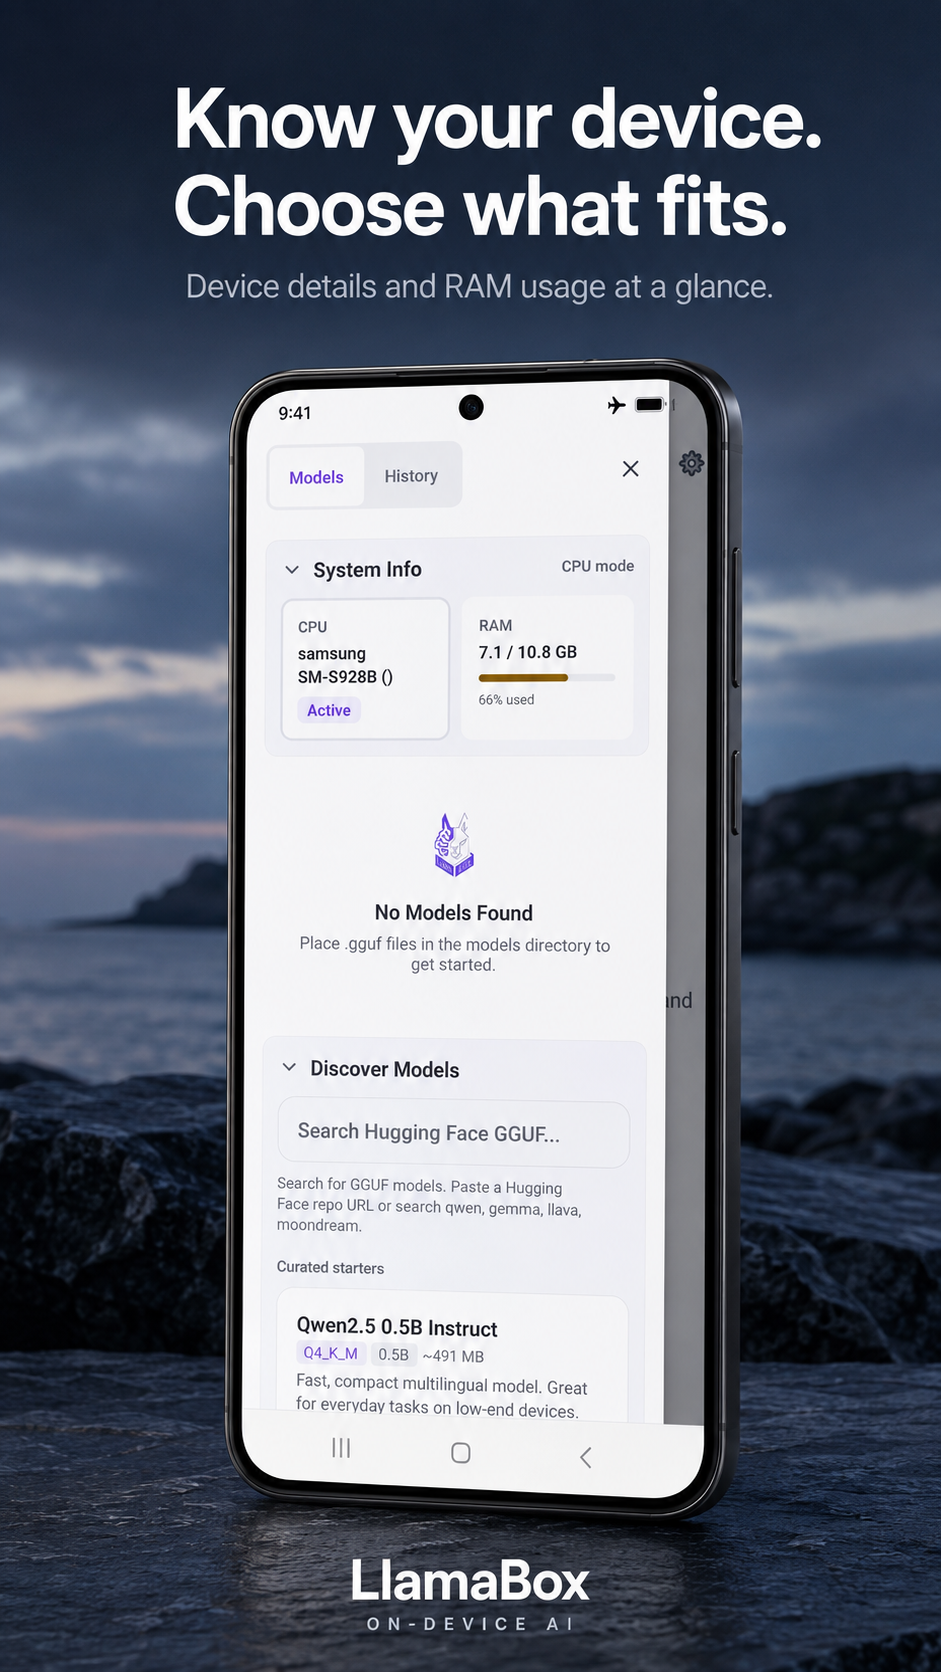
Live RAM / CPU insight while a model is loaded — know what your phone is carrying.
JSI/TurboModules for streaming tokens without legacy bridge tax. Zustand + SQLite + AsyncStorage — each store does one job well.
A compatibility trade-off, not a speed claim. Avoiding device-specific acceleration means fewer dependencies and broader Android support.
From install to private chat without wiring your life to someone else’s compute cluster.
Android 7.0+ arm64. Install from Google Play — package com.llamabox.
In-app download or import. Start small (~0.5–1B Q4) on mid-range phones.
Optional airplane mode. Tokens generate on-device; history stays in local SQLite.
Specific, checkable statements instead of adjectives. Where a claim cannot yet be verified from public source, we say so.
Full detail: network behavior · architecture · privacy · llms.txt · tested devices
Read 10 short guides, preview the illustrated pages and keep the original PDFs. No signup needed.
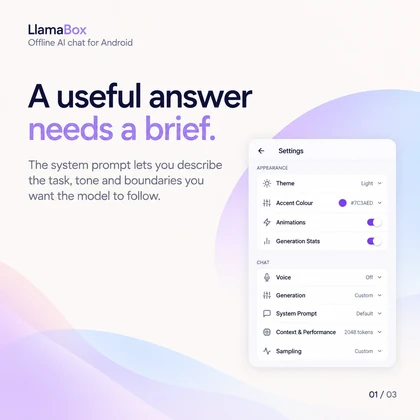
Explore models, device information and generation controls. Select a product preview to view it full size.
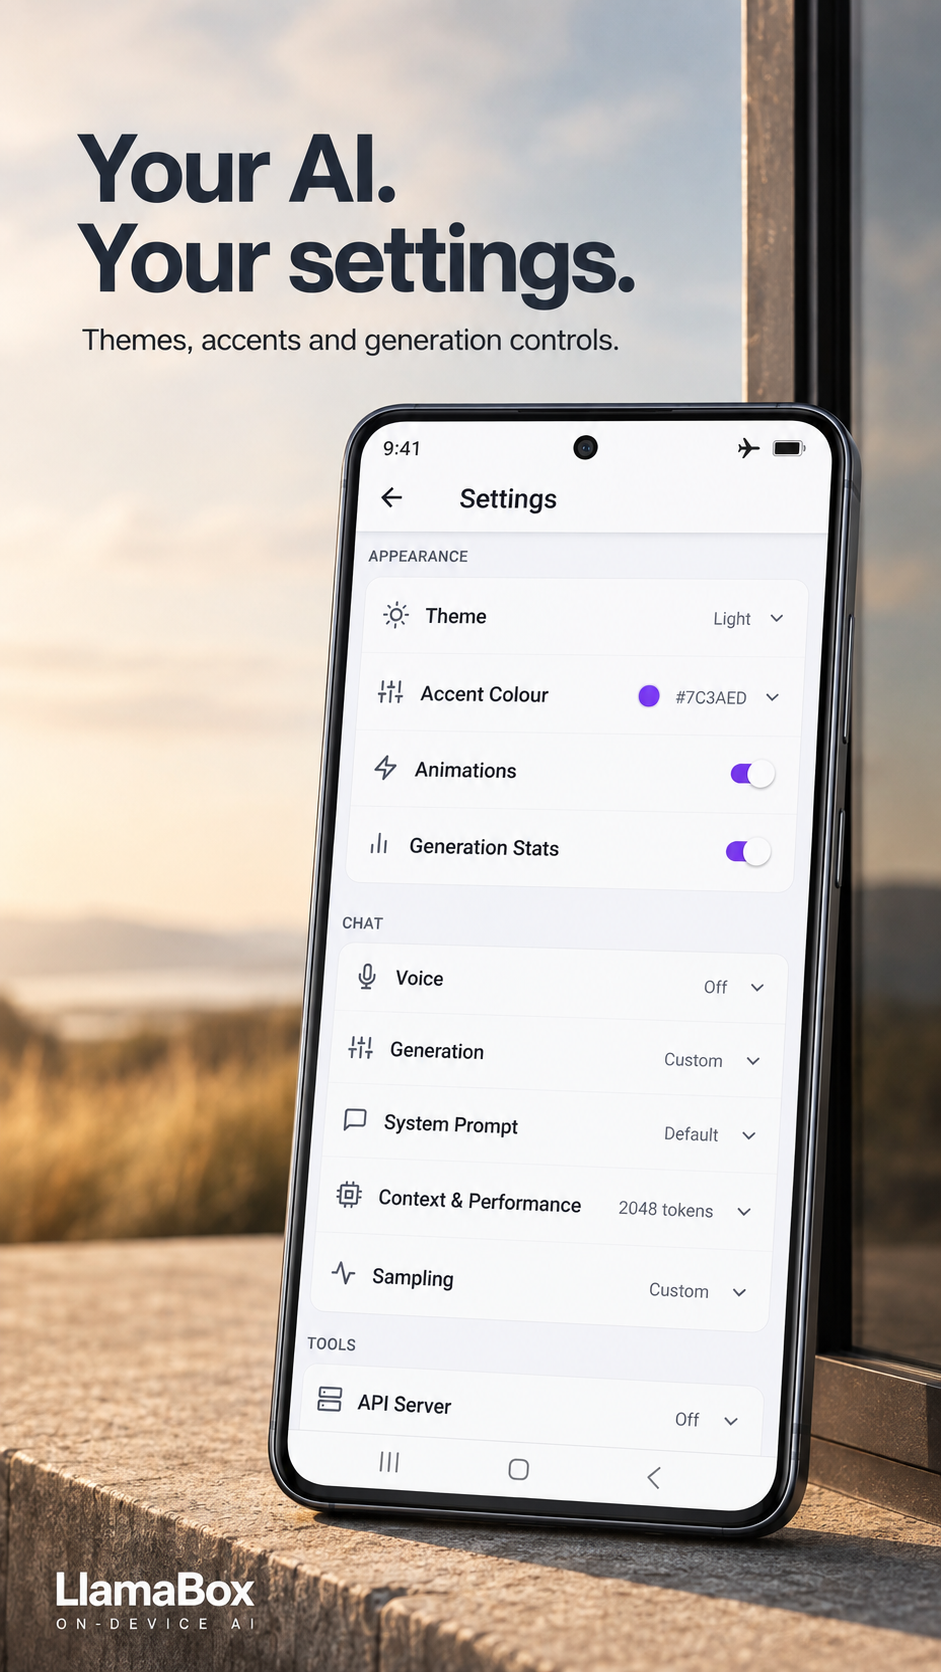
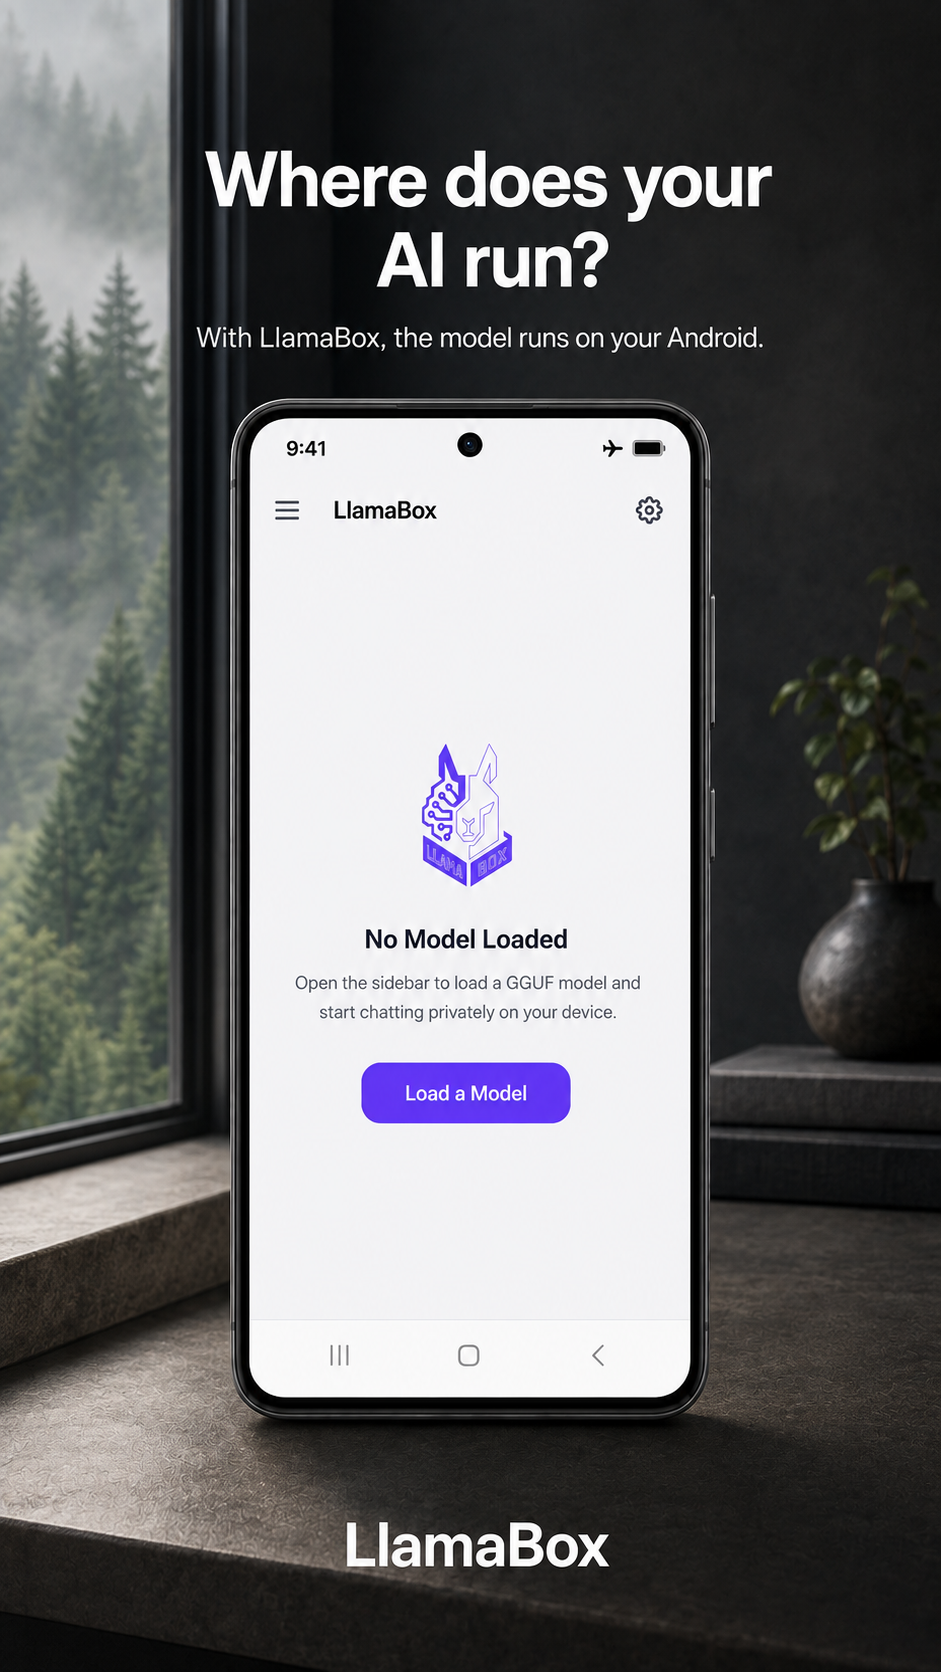
Performance varies by phone, model, quantization, context and thermal state. Results appear only after a measured run is recorded.
Deep dive: architecture docs · llms-full.txt for AI agents.
The most useful thing we can publish is a real measurement matrix. The component and schema exist now; rows appear as verified runs are recorded.
| Device | Android | RAM | Model | Quantization | Load time | Generation | Result |
|---|---|---|---|---|---|---|---|
|
No verified device measurements are published yet. Device benchmark runs are being collected on real hardware. See tested devices for the schema, methodology and how to contribute a run. |
|||||||
Cloud assistants win on raw model size. LlamaBox wins when the data must not leave the room.
| Capability | LlamaBox | Typical cloud AI app |
|---|---|---|
| Inference location | On your phone | Vendor servers |
| Works offline | Yes, after a model is stored on the device | No |
| Account required | No | Usually yes |
| Conversation telemetry | No app analytics or conversation telemetry SDK | Policy-dependent |
| Independently auditable | Not yet — source release planned | Trust the vendor |
| Largest frontier models | Bounded by device RAM | Yes |
| Vision on-device | Supported with compatible model + mmproj | Commonly processed on provider servers |
If a device cannot run a model well, we would rather you learn that here than after a 3 GB download.
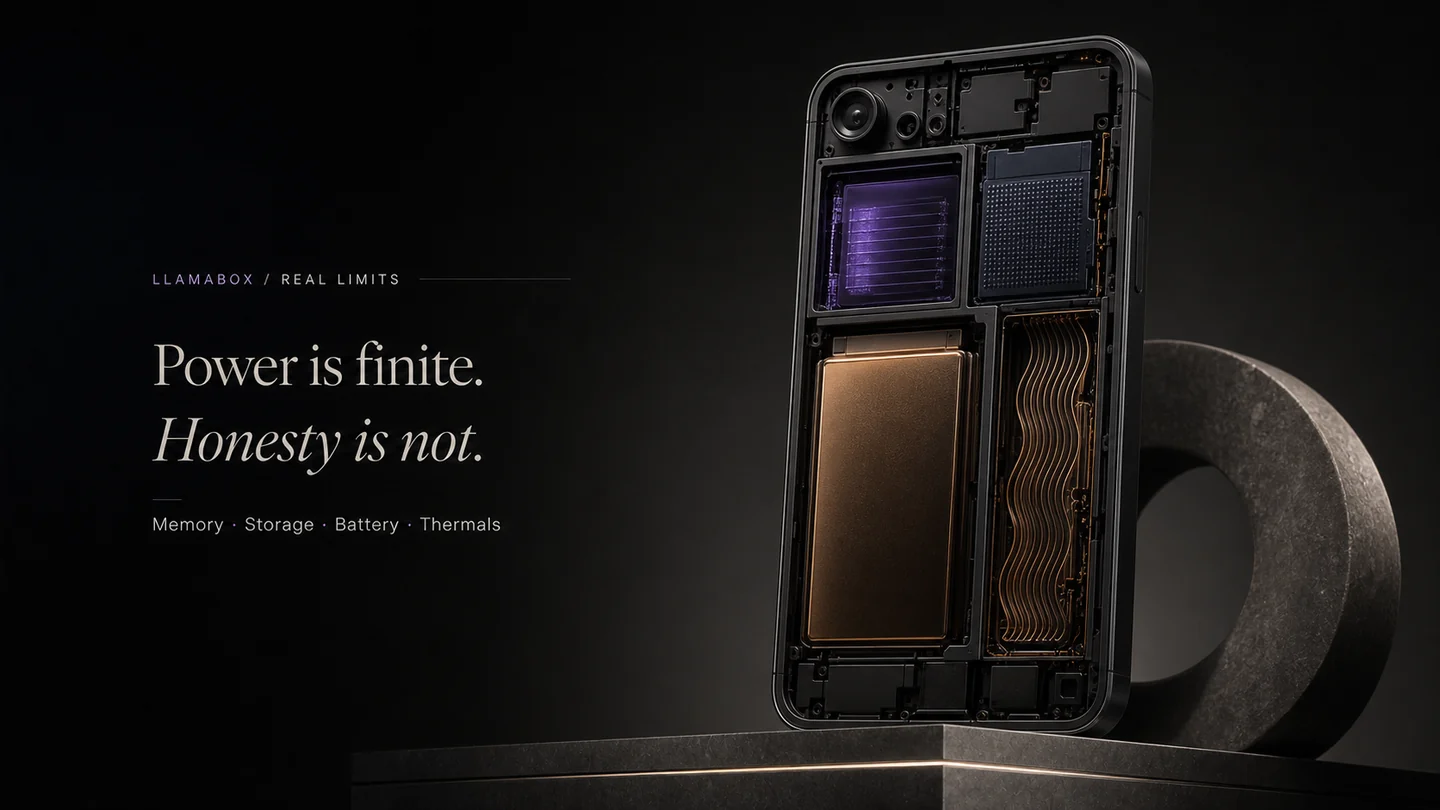
Local models are far smaller than frontier cloud systems. Expect weaker reasoning, less world knowledge and more errors.
Token rate depends on your specific CPU and memory bandwidth. There is no single number we can promise.
Available RAM caps usable model size. Android may reclaim memory and interrupt generation.
GGUF files run from hundreds of megabytes to several gigabytes.
Sustained CPU inference drains the battery noticeably faster than ordinary app use.
Long generations heat the device; the SoC will slow itself down to compensate.
Older devices process long prompts slowly, which delays the first token.
GGUF is a container. Support depends on whether the bundled llama.cpp build handles that specific architecture.
Multimodal use needs a matching mmproj file alongside the base model. Mismatches fail to load.
The current build does not use GPU or NPU acceleration.
Models carry their own licenses and usage restrictions, separate from the LlamaBox app.
Initial download plus first model load is the slowest part of the experience.
Context: performance data · architecture · tested devices
Citable facts for humans — and for answer engines via schema + llms.txt.
Commercial licensing, enterprise deployment and OEM integration for managed devices, regulated environments and low-connectivity operations.
Get it on Google Play. Bring a phone. Leave the cloud behind.